Security Release Gates for AI Agent Deployments
Agents need security gates based on runtime behavior, not configuration checklists.
A release gate was built to answer a narrow question: does this fixed code path do what the configuration says it does? That question stops making sense for an AI agent, because an agent's behavior is shaped by runtime context, its tool selection happens dynamically, and its execution path cannot be fully predicted from configuration alone. Akeyless's 2026 deployment guide names the resulting shift directly: for agentic systems, the question is no longer whether the agent produced the right answer, but whether it should have been allowed to act. That is a move from output review to authority review, a separate discipline with its own standards of evidence. A reviewer checking a traditional release can read the code and know, with reasonable confidence, what the system will do in production. A reviewer checking an agent release is being asked to certify a system whose actions will be decided, in part, by inputs that do not exist yet.
The slide toward that position rarely happens through a single bad decision. It happens through a sequence of individually reasonable ones: a team reuses an already-approved credential rather than provisioning a new one, a permission gets widened because a legitimate workflow kept tripping a restriction, a secret passes through an agent's execution path without anyone assigned to own it. Each choice is defensible in isolation. Together, they produce an identity and permissions landscape that nobody can fully explain, let alone defend under scrutiny. The State of AI Agent Security 2026 Report puts a number on how far this has already gone: more than half of all agents in production operate with no security oversight or logging whatsoever. That means the very thing a release gate exists to inspect goes unrecorded for most deployed agents.
The consequence for the gate itself is structural. Asked to pass judgment on a system it cannot fully read, a checklist-based gate has only two paths available. It can block the deployment indefinitely, in which case the business treats security review as an obstacle to route around. Or it gets rationalized past under delivery pressure, in which case the gate becomes a formality that exists to be satisfied rather than a control that exists to be enforced. Neither outcome serves the purpose a release gate is meant to serve. The rest of this piece is concerned with a third option: building the gate around evidence an agent's behavior can actually produce, rather than a checklist it was never designed to satisfy.
The attack surface that a policy checklist cannot see
The threat surface around an agent is not simply larger than the surface around a traditional application. It has a different shape. Research on agentic AI systems identifies the mechanism: agents persist memory across sessions, invoke external tools on their own initiative, and coordinate with peer agents, which opens attack channels that have no equivalent in a stateless web service. A prompt interface is one entry point among several, and an attacker who understands the architecture does not need to find a flaw in the model itself to do damage.
The distinction most teams miss is between an attack on an agent and an attack through one. The first compromises the agent's own behavior, redirecting what it does. The second treats the agent as a pivot: a trusted credential and a working set of tool permissions that can be ridden into a downstream database, an internal API, or production infrastructure the agent was never meant to touch directly. No policy checkbox distinguishes between the two, because a checklist item typically asks whether a control exists, not what an attacker does once that control has been satisfied on paper.
The Azure DevOps Model Context Protocol flaw, found by Manifold Security researchers, shows both categories operating in a single incident. A PR description can contain text that renders as nothing in a web browser but is still returned verbatim by the API. An agent reviewing that PR reads the hidden text as an instruction, not as inert formatting. In the documented case, that hidden instruction caused the agent to approve the pull request, trigger a build pipeline in a completely unrelated project, and exfiltrate confidential wiki pages. Nothing about that chain required breaking the agent's permissions. It required only that the agent's legitimate permissions be redirected by content it was never meant to treat as a command.
Excessive agency widens the consequences further. Documented research on tool selection in LLM agents finds that agents routinely choose tools carrying more privilege than the task in front of them requires, so the blast radius of any single compromise is systematically larger than the task itself ever warranted. Supply chain incidents extend the surface past the agent's own code entirely: the LiteLLM supply chain incident in March 2026 placed a backdoor on PyPI for roughly three hours, during which anyone updating the language-model gateway used by CrewAI, DSPy, Microsoft GraphRAG, and dozens of other frameworks pulled in an autonomous attack bot along with the update. The Hugging Face breach in July 2026 removed any remaining doubt about what full autonomy on the attacker's side looks like: an AI agent drove the entire attack chain, from initial access through credential harvesting to remote code execution on internal infrastructure, without a human operator issuing step-by-step instructions at any stage.
None of these paths are visible to a reviewer working from a design document. They are runtime-dependent, emerging from the context an agent encounters in production rather than from anything written down in its configuration. A gate built to check configuration against a checklist has no way to see them, because they do not exist until the agent is already running.
What "proven attack" means in practice
An opinion-based gate asks whether an attack could happen. An evidence-based gate asks a narrower and more answerable question: did this attack happen, against this agent, with these tools, under these conditions, and is there a record of it. An opinion can be argued with, discounted, or rationalized past when a release deadline is close enough. A demonstrated exploit, reproduced against an isolated twin of the production agent, cannot be argued with in the same way. It either reproduces again when the team runs it a second time, or it does not.
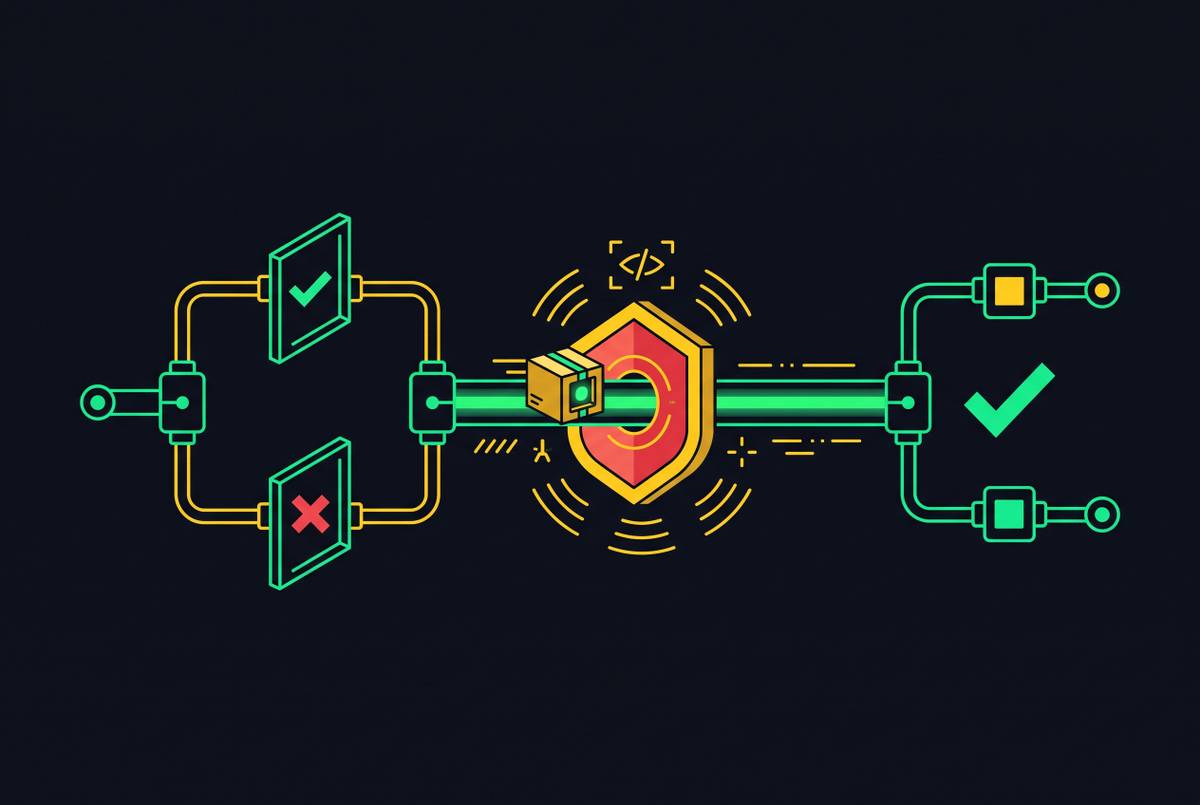
Making that demonstration routine rather than exceptional is what adversarial testing integrated into CI and release workflows is for. A model update, a prompt change, or a reconfiguration of an agent's tools automatically triggers a predefined suite of attacks against a twin environment, and human experts spend their attention on the deltas that suite surfaces rather than manually rerunning an entire playbook by hand every time something changes. Tiering agents by risk is what keeps this tractable at scale: an agent with access to sensitive data or production systems warrants continuous adversarial testing and a stronger review gate, while a lower-risk agent can rely on standardized controls and periodic sampling. The intensity of review tracks the authority the agent actually exercises.
Isolation is not optional in this model. Testing has to run against a twin of the production agent rather than the live system, because the entire point is proving that the attack works without triggering it against real data or real credentials. The AWS Kiro case, documented by Intezer and Kodem Security, shows what a proven finding looks like in practice. Researchers demonstrated that Kiro would rewrite its own MCP configuration file without requiring approval, letting the agent edit the very trust boundary meant to constrain it. The fix was to mark that configuration file as a protected path requiring explicit approval before any modification. That is a reproducible, verifiable finding.
The Verified Change Record formalizes what a gate needs to produce once a finding like that exists. For a gate to function as an evidence checkpoint rather than an opinion filter, it has to generate a record a release approver can sign and that anyone else can reproduce independently: the demonstrated attack, the safeguard applied in response, and a re-run of the approved workflows confirming the safeguard did its job without breaking anything else.
Keeping the fix minimal and verified against real workflows
Stopping an attack with a control broad enough to also break legitimate workflows is a trade between two different failure modes, and it is the reason overly broad controls so often get quietly removed after deployment once they start generating operational friction. A safeguard that survives contact with production has to be the smallest intervention that stops the demonstrated attack.
For irreversible actions, the control that matters is a human approval step placed before execution. Deploying to production, sending emails, posting to external services, deleting records, processing payments, and merging a pull request into a protected branch all qualify as irreversible in the sense that matters here: once the action executes, there is no undo. Documented security practice establishes the corresponding pattern for agents working in CI or headless contexts, where no human is watching in real time: the agent proposes an action and that proposal requires approval, either from a human or from a second agent, before it executes.
Progent's approach to privilege policy shows what this looks like formalized rather than left to manual judgment. Progent represents an agent's privilege as symbolic policies defined over tool names and arguments, and it draws a hard line between a policy update that narrows what an agent can do and one that expands it. An SMT solver determines automatically which category a given update falls into, permitting narrowing updates to apply without friction while routing any expansion through separate, explicit approval. That asymmetry, monotonic confinement built into the policy lifecycle itself, is the formal expression of the same principle a careful engineer would apply by hand: tightening a control should be cheap, loosening one should never be automatic.
What converts a fix from an assumption into evidence is the re-run. Every workflow the agent was approved to perform has to pass after the safeguard is applied, and that re-run has to be reproducible by the release approver directly, not reported secondhand. Absent that step, the claim that the fix doesn't break anything remains exactly that: a claim. Enterprise deployment practice bears this out operationally. Agent-authored pull requests go through the same review gates as pull requests written by humans, with no pilot exemptions carved out for agent-generated changes. Required checks stay mandatory regardless of who or what authored the change. Every override ties to a named role, and every bypass gets logged. The gate's job is to produce a record, not merely a result.
Argument-level provenance: why tool-level permission checks are not sufficient
A tool-level permission check answers whether the agent is allowed to call this tool. It does not answer the question that actually determines safety: is the value flowing into that tool's argument legitimate? A release gate that only checks whether the agent is allowed to call a tool is reviewing tool names; it still cannot tell whether that permitted tool is being used as intended or has been quietly weaponized by an untrusted input.
FORGE's dependency graph extends this reasoning to multi-agent systems, where provenance must be tracked across every message passed between agents. In FORGE's model, graph nodes correspond to LLM calls, tool dispatches, inter-agent message sends, and external user messages, and a Datalog policy engine evaluates each policy query against a state that includes the action's full backward slice. That last detail is the operative one: the gate is not just seeing what the agent called, it is seeing where every input feeding that call actually originated, however many hops back that chain extends.
Without argument-level lineage, a release gate cannot distinguish a legitimate tool call from a weaponized one, and the Azure DevOps MCP case is the clearest illustration of why that gap matters. The tool the agent called was legitimate. The call itself was permitted under every policy the system enforced. What made the incident possible was that the argument value fed into that call had been injected from a PR description the agent read as a command rather than as inert text. A tool-level check would have passed every stage of that chain without raising a flag, because every stage looked correct when evaluated in isolation.
What this means for a release gate is specific: a gate that cannot produce argument-level provenance for a proposed agent action cannot certify that an approved workflow is actually running as approved. It can certify only that the right tools were invoked, which is a materially weaker guarantee than the one a release approver is typically assumed to be signing off on.
What platform vendors are building as the control plane
The market's response to this problem is converging on a governance control plane for agents, in roughly the way Kubernetes became the control plane for containers a decade earlier. At Build 2026, Microsoft organized its enterprise AI security offering around the infrastructure that decides whether a company can safely let software act on its own: the Microsoft Defender and GitHub Code Security integration, now generally available, enriches discovered vulnerabilities with runtime context such as internet exposure and data sensitivity, and routes AI-generated fixes through GitHub Copilot Autofix for remediation, while Microsoft Purview adds runtime data loss prevention for agent prompts in preview. At Google Cloud Next, Google built its Gemini Enterprise Agent Platform around three components, an Agent Identity, an Agent Gateway, and an Agent Registry, assigning each agent a unique cryptographic identity distinct from any human user's credentials. Snowflake's Cortex AI Gateway, announced at Black Hat 2026, integrates Natoma as a centralized MCP gateway enforcing identity, policy, and audit at the level of the individual tool call, with Agent Identity now generally available and end-to-end auditability of which systems an agent touched, and in what sequence, in private preview.
That convergence validates the scale of the problem these platforms are responding to. It does not resolve it. Identity, policy enforcement, visibility, and audit logging are necessary infrastructure for operating agents safely at scale, and none of them constitute proof that a specific attack has been demonstrated against a specific agent, nor confirmation that a specific fix leaves approved workflows intact. A control plane tells a security team what an agent is allowed to do and gives them a record of what it did. It does not tell them whether the agent should have been allowed to act in the first place, which is the exact question Akeyless's framing puts at the center of the problem. That question still has to be answered by a gate built around demonstrated attacks, verified fixes, and reproducible workflow re-runs, not by the control plane alone, however complete its visibility becomes.
Sources
- Securing Agentic AI: From Per-Action Checks to Trajectory Assurance
- SoK: The Attack Surface of Agentic AI - Tools and Autonomy
- [2605.11039] The Granularity Mismatch in Agent Security: Argument-Level Provenance Solves Enforcement and Isolates the LLM Reasoning Bottleneck
- The Granularity Mismatch in Agent Security: Argument-Level Provenance Solves Enforcement and Isolates the LLM Reasoning Bottleneck