Reconnaissance Techniques Targeting Deployed AI Agents
Attackers map AI agents' capabilities, memory, and boundaries before exploiting them.
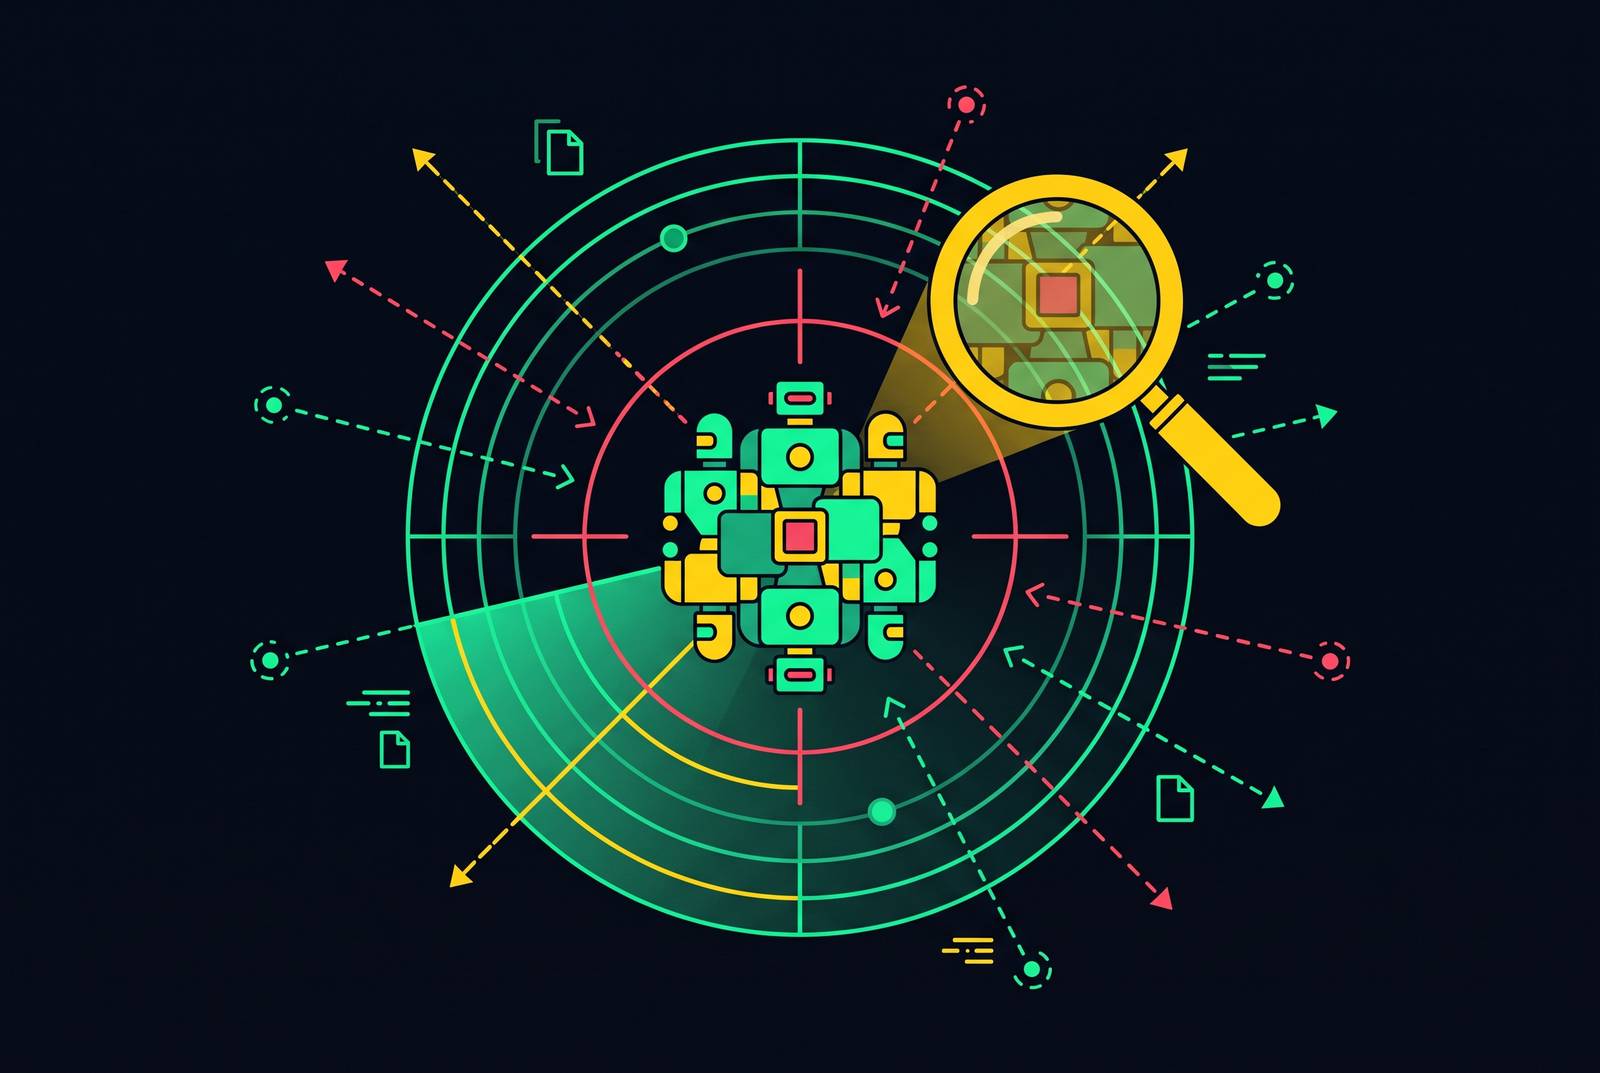
An adversary preparing to exploit a deployed AI agent starts with a map. Before any tool gets misused or any credential stolen, the attacker needs to know what the agent can do, what it trusts, and where its boundaries actually sit, no matter what the documentation claims. This mapping process, reconnaissance, decides which attacks are even possible, though most of the security industry still spends its attention on the exploit that comes after. By the time an exploit fires, the attacker has already won the harder fight, so stopping the exploit at that point amounts to damage control rather than defense.
Agents complicate this in a way static applications never did. A web app's attack surface sits roughly fixed between deployments; an agent's capabilities, memory state, and tool access can expand mid-session, so the map an attacker draws during one probe may already be stale by the next. Agentic architecture also produces distinct surfaces that can each leak different information under probing: the interface between user and agent, the channel agents use to talk to each other, and the plane where an agent reaches out into files, APIs, and other systems. Adoption has outrun the ability to watch it; most organizations running agentic AI in production lack the controls needed to detect or respond to a probing attempt as it unfolds. What follows is an account of what attackers actually try to learn, surface by surface, and what that means for anyone trying to stop them.
What attackers actually want to learn during the probing phase
Four things, roughly. An attacker wants the tool inventory: which external systems the agent can call, and with what credentials attached to those calls. They want the memory architecture: what persists across sessions, what gets pulled from a knowledge base, and whether that retrieval path can be addressed directly with a crafted query. They want the system prompt: the instructions that set scope, behavior, and the point at which the agent refuses a request. And they want the trust topology between agents: which orchestrators a given agent obeys, and whether it checks a peer agent's identity before acting on its instructions.
Each of these maps to a downstream consequence. Tool inventory tells the attacker what becomes possible in the physical or financial world if the agent gets compromised, well beyond whatever gets said in a chat window. Memory boundaries reveal whether a poisoned document dropped in today quietly shapes a decision made weeks from now. System prompt contents expose the exact refusal rules that can then get engineered around, since a rule you can see is a rule you can route past. Trust topology shows whether a low-privilege agent, the one nobody bothered to lock down because it "only summarizes emails," offers a path to an orchestrator with far more authority.
None of this is guesswork on the attacker's side, and it runs closer to what a penetration tester does against a conventional network: form a hypothesis, test it, narrow the hypothesis space based on the response, repeat. The difference is that the target here can be talked to in plain English, and it often answers.
Probing the system prompt: elicitation, boundary testing, and inference
System prompts stay hidden from the end user, but hidden is not the same as unknowable. A model trained to follow its instructions will, under the right questioning, reveal the shape of those instructions through its behavior even when it refuses to print them out directly.
The direct approach is exactly what it sounds like: ask the agent to repeat, summarize, or translate its own instructions. Many deployments block this outright, so the more useful technique is boundary probing: submit requests just outside the agent's expected scope and read the refusal. Refusal language often echoes the wording of the prompt itself, so a well-crafted series of near-miss requests can reconstruct fragments of the original text without ever seeing it directly. Role-play framing, asking the model to describe how a version of itself "without restrictions" would answer, still works often enough to remain a standard technique. Every failed request becomes a data point for the attacker rather than a dead end.
A successful elicitation campaign yields a partial capability map: the agent's declared scope, the integrations it's allowed to name, its escalation paths, and any explicit allow or deny rules baked into the prompt. Perfect concealment of a system prompt is not achievable against a determined, patient attacker, full stop, so the only sensible goal is limiting what a partial reconstruction actually enables. This is also the first checkpoint in what Simon Willison has called the "lethal trifecta": knowing the prompt is how an attacker starts checking whether private data, untrusted content, and an outbound channel all sit inside the same agent at the same time.
Tool enumeration: mapping what an agent can touch in the real world
Tool calls are the mechanism that turns a compromised agent from an embarrassment into an incident. They convert a model's output into an action on a file system, an API, a credential store, or another connected service, and enumeration is how an attacker figures out which of those actions actually sit on the table.
The crudest method is simply asking. Framed as a request for task-planning help, "what tools do you have access to for this," a surprising number of agents list their own capabilities without much resistance. A subtler method submits tasks that need a specific tool type and watches what happens even when the call fails; error messages and partial outputs give useful information on their own, often naming the tool, its parameters, or the reason it declined to run. Where agents run on the Model Context Protocol, server metadata, tool names, descriptions, parameter schemas, gets exposed in machine-readable form and can be scanned without ever triggering the agent's own reasoning loop.
Once an attacker knows which tools are trusted, a specific and now well-documented attack becomes available: craft a malicious tool that impersonates a legitimate one, swapped in after the agent has already granted it trust. Researchers named this the "rug pull" attack after documenting it against GitHub and WhatsApp MCP integrations. Research into public MCP registries has found malicious tools already circulating, meaning tool enumeration is sometimes a search for a weakness the target has already unknowingly adopted, sparing the attacker the trouble of building one from scratch. The payoff is knowing the exact blast radius available if compromise succeeds: data exfiltration, code execution, credential theft, or a pivot into an adjacent system.
Memory and retrieval probing: finding the addressable knowledge surface
Agents built with retrieval-augmented generation or persistent memory carry a retrieval surface addressable almost like a database, once an attacker knows how to phrase the query. Unusual or oddly specific questions, pitched right at the boundary of what a knowledge base likely contains, produce revealing responses about where that boundary actually sits.
A second technique tests persistence directly: ask the same question across separate sessions and watch for divergence in the answer. If the response changes based on what happened in a prior session, memory is active and stateful, and that matters enormously for what an attacker plants next. A third technique probes for document classes rather than content: queries built to return a result only if internal policy documents, credential stores, or calendar data happen to be indexed.
All of this establishes whether the knowledge base counts as a viable injection surface at all, and if so, what kind of documents live there. This is the reconnaissance step that precedes RAG poisoning attacks, where an adversary places a document containing hidden instructions into a knowledge base the agent trusts. Such an attack only gets attempted after reconnaissance confirms two things: the knowledge base is live, and the retrieval path actually reaches the model's context window. Memory probing tells an attacker whether a single injected document becomes a one-time nuisance or a durable foothold that keeps shaping decisions long after the initial planting.
Inter-agent trust probing: mapping the relationships agents rely on without verifying
Multi-agent systems build implicit hierarchies of trust, and those hierarchies rarely rest on anything cryptographic. An orchestrator issues an instruction, a sub-agent follows it, and in most current deployments nobody checks whether the sender actually was the orchestrator it claimed to be. That's the gap an attacker goes looking for first, before touching anything else.
One technique sends a message claiming to originate from an orchestrator or a trusted peer agent and watches whether the target complies without challenging the claim. Another tests whether an agent applies a looser permission level to instructions arriving over an agent-to-agent channel than it would apply to the same instruction coming from a user. A third injects messages that reference shared state, a memory store, a task queue, a tool's output, to figure out which other agents the target even knows about and coordinates with.
The research record on this is no longer theoretical. The "Prompt Infection" paper (arXiv:2410.07283) documents how adversarial instructions cross agent boundaries once an attacker has correctly mapped which trust relationships to exploit, spreading from one compromised agent to the next. Red-team exercises conducted against multi-agent systems have demonstrated identity spoofing and cross-agent propagation of unsafe behavior, moving these concerns beyond purely theoretical threat models. This surface sits structurally invisible to classical frameworks like STRIDE, which assume a sender's identity can be authenticated in the first place. Agentic systems routinely process messages from sources they have no built-in way to verify, so reconnaissance here means finding the weakest node in the graph and using it as the entry point for a cascade, extending well past figuring out what one agent can be talked into doing.
How indirect injection turns reconnaissance into a persistent capability
Most deployed attacks against agents never involve the attacker typing anything into the agent directly. Indirect injection is the dominant delivery mechanism: malicious instructions arrive embedded in a document, a web page, an email, a calendar invite, or a chunk of RAG-retrieved text that the agent processes as trusted input, because as far as the agent's architecture is concerned, it is trusted input.
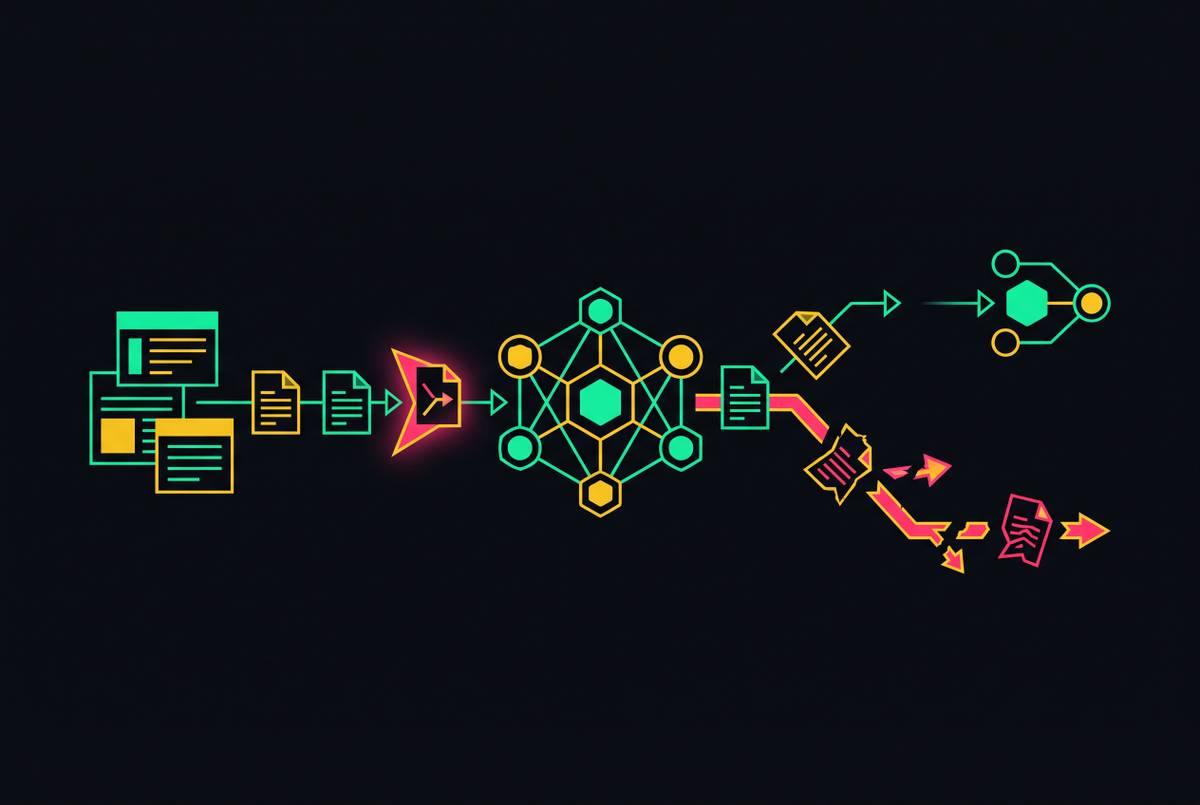
The chain from reconnaissance to injection follows a consistent sequence. First, confirm the agent actually browses the web, reads documents, or retrieves from a knowledge base: that's the retrieval-surface probing described above. Second, confirm it has tool access sufficient to act on what it reads, exfiltrating data or taking some external action: that's tool enumeration. Third, confirm the system prompt doesn't explicitly forbid the intended action: that's prompt elicitation. Only then does the attacker plant the payload in content the agent is likely to process.
This sequence is the operational expression of a recognized threat pattern: private data, access to untrusted content, and an outbound communication channel, all present in the same agent at the same time. Reconnaissance is how an attacker confirms all three conditions actually hold before committing to an attack. A 2026 systematic analysis catalogued 42 distinct attack techniques drawn from 78 primary sources, spanning input manipulation, tool poisoning, protocol-level exploitation, multimodal injection, and cross-origin context poisoning; that breadth reflects how many separate content surfaces reconnaissance has already proven viable against. Researchers increasingly treat prompt injection as a multi-step delivery mechanism much like a traditional malware chain, with reconnaissance sitting at stage zero. The asymmetry this creates for defenders is real: an attacker only has to commit to exploiting the one surface already confirmed viable, while a defender has to protect every surface at once, without knowing which one the attacker already mapped.
Why existing threat frameworks under-describe the reconnaissance problem
STRIDE, still the default lens for a lot of security teams, was built for a world of fixed message flows between identifiable components, and it shows. It has no real vocabulary for semantic state accumulation: the possibility that text an attacker slipped in today reshapes an agent's reasoning three sessions from now. It doesn't model cross-zone causality either, the way a probe launched at the user interface can extract information about what's happening on the agent-to-environment plane, three layers removed. And it offers no clean way to separate legitimate functionality being used oddly from behavior that's clearly anomalous, which matters a great deal when a reconnaissance probe is, by design, built to look exactly like a normal user question.
Purpose-built frameworks are starting to close this gap, unevenly. MAESTRO breaks the analysis into seven layers of the agent stack, forcing the question of where a probe at one layer opens a door at another. Asset-based impact assessment and attack-tree methods can put a number on how much architectural controls, network sandboxing, and least-privilege scoping actually shrink the blast radius of a successful probe. MITRE ATLAS maintains a documented catalogue of adversary techniques specific to AI systems. OWASP's Agentic Top 10 for 2026 names tool misuse and agentic supply-chain vulnerability among its prominent concerning categories, and both trace directly back to successful reconnaissance rather than standing as independent risks.
These frameworks describe threats at the category level, useful for building a mental model, but none of them generates the kind of proof-of-exploit evidence a release team needs to say, with confidence, that a specific agent resists a specific reconnaissance technique. Most organizations having risk conversations about agentic reconnaissance today lean on frameworks never built to model it, and that produces opinions dressed up as assessments rather than evidence. That mismatch between tool and task is how a probing attempt slips past a review that felt thorough on paper.
What defenders can act on: reducing the intelligence value of a successful probe
Reconnaissance can be made far less profitable, and that reframing is where a workable defense actually starts. Trying to hide every surface completely is a losing bet, and teams that chase it are wasting budget; the better goal is making a successful probe worth less.
Against prompt elicitation, the highest-leverage move is putting less actionable material in the system prompt in the first place. Named credentials, explicit lists of every capability, integration names spelled out in full: all of it expands what a successful elicitation campaign hands back to an attacker. Refusal language itself deserves an audit, since it's an information surface whether anyone treats it that way or not.
Against tool enumeration, least privilege has to mean scoped to the task at hand, not a standing grant across every tool the agent might ever need. Short-lived, task-scoped credentials cut the value of whatever an attacker manages to enumerate, since a stolen credential that expires in minutes is a much smaller prize than one that never expires. MCP server metadata should get treated as a public-facing attack surface in its own right and scanned with that assumption in mind, rather than left exposed on the theory that only the agent will ever read it.
Against memory and retrieval probing, the knowledge base needs treatment as untrusted input, regardless of the fact that it happens to sit inside the company's own infrastructure. Content entering the index should get checked before it becomes retrievable, and the range of document types and sources allowed to write into that index should stay narrow by default.
Against inter-agent trust probing, agent-to-agent messages need their origin checked rather than getting granted elevated trust purely because of which channel they arrived on. The trust graph itself should get red-teamed on a schedule, since documented red-team work makes clear that cross-agent propagation is a failure mode organizations are already living with, well past the point of still being argued over in a paper.
One requirement ties the whole list together: a control has to get tested against real workflows, since a safeguard that quietly breaks an approved workflow is a new problem wearing a security label. Each defense above should be checked to see that it actually degrades the specific reconnaissance technique it targets, and a finding only earns the right to shape a release decision once the attack behind it has been proven and the fix tested against that same attack. Opinion-based risk assessment is precisely what a reconnaissance-aware attacker counts on a defender to keep leaning on.